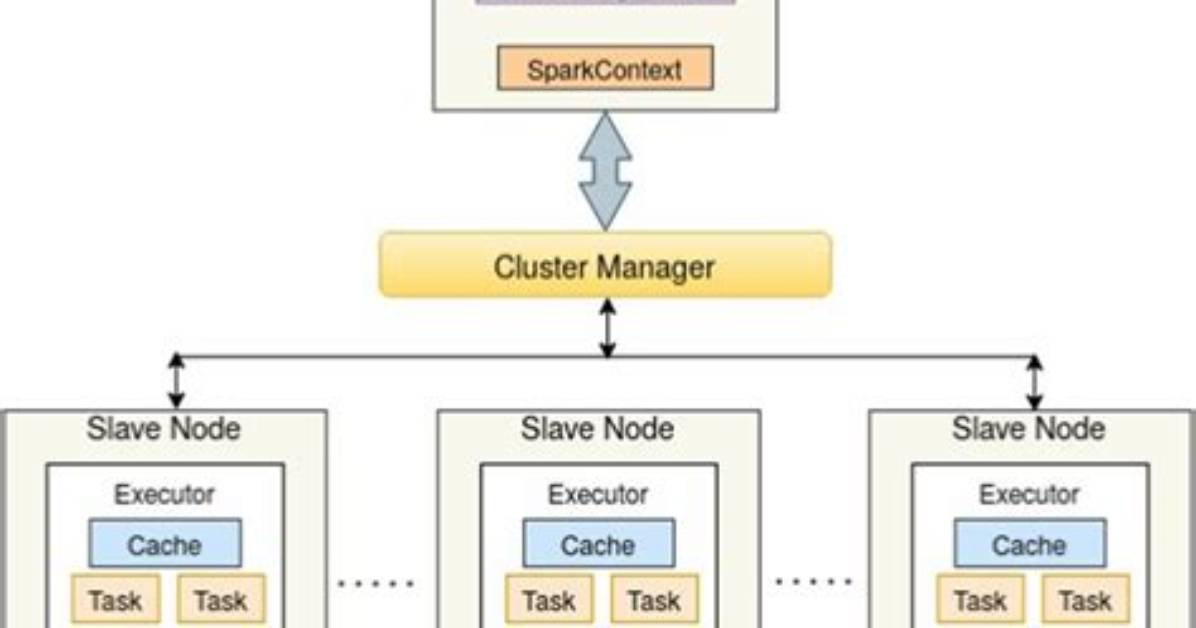
This section addresses frequently asked questions (FAQs) about memory per executor Spark. These FAQs provide concise and informative answers to common concerns or misconceptions related to this topic.
Question 1: How does memory per executor affect Spark application performance?
Answer: Memory per executor is a crucial factor that significantly influences the performance of Spark applications. If each executor has insufficient memory, it will struggle to hold the required data in memory, leading to excessive spilling to disk. This spilling process can severely impact performance as disk I/O operations are significantly slower than in-memory operations.
Question 2: How do I determine the optimal memory per executor for my Spark application?
Answer: Determining the optimal memory per executor requires careful consideration of several factors, including the size of the data being processed, the number of executors, the amount of overhead, concurrency, data locality, and the amount of shuffle data.
Question 3: What are the consequences of allocating too little memory per executor?
Answer: Allocating too little memory per executor can result in insufficient memory to hold the necessary data in memory, leading to excessive spilling to disk. This can significantly degrade application performance due to the slow nature of disk I/O compared to in-memory operations.
Question 4: What are the consequences of allocating too much memory per executor?
Answer: Allocating too much memory per executor can lead to underutilized executors, where they are not fully utilizing their allocated memory. This can result in inefficient resource utilization and potentially higher costs.
Question 5: How does data locality impact memory per executor?
Answer: Data locality refers to the proximity of data to the executors that will process it. Good data locality can reduce the amount of data that needs to be transferred over the network, which can improve performance and reduce the memory overhead associated with network buffers.
Question 6: How does shuffle data affect memory per executor?
Answer: Shuffle data refers to data that is exchanged between executors during certain operations. Large amounts of shuffle data can put a strain on the memory resources of both the source and destination executors, especially if the data cannot fit in memory and needs to be spilled to disk.
By understanding these FAQs and considering the factors discussed, you can optimize the memory allocation for your Spark executors, ensuring efficient and performant Spark applications.
Transition to the next article section:
This concludes our exploration of memory per executor Spark. In the next section, we will delve into advanced topics related to Spark memory management and performance tuning.

